Business Keyword Modeling
Business Keyword Modeling enables you to train and publish models that can auto-populate ontology fields by identifying business keywords. Keyword identification leads to document source identification, and this enables the application to lookup for source specific information in the database. If the information is available, it is used to auto-populate the ontology fields as per the requirements. Auto-populating saves time as it is quicker than the regular OCR-and-rule based extraction and more reliable.
Note
The accuracy and reliability of the models in finding correct data depends upon how well they have been trained.
To use business keyword modeling for a given subtype of documents, the subtype must include a field of Source Name type.
 Unique Word Unique Couple (UWUC) concept
Business keyword models internally use UWUC concept. Here, unique values, which can be a single word or a couple of words, are sampled from a batch of documents and categorized based on their type, say as SSN, PAN, telephone, etc. Using ML, the underlying data pattern for a given category of values is found. For example, a telephone number may have a pattern ddd-ddd-dddd, where 'd' represents a digit. When the models are applied to documents that are to be processed, they attempt to find these patterns in given documents. Data fields that are found to have a matching pattern are assumed to be of the type as indicated by the pattern category.
To open Business Keyword Modeling page, go to the main menu, and then under TruCap+ Studio, click Business Keyword Modeling.
Following activities are involved in publishing a business keyword model:
-
Labeling and annotating keywords (See Keyword annotation.)
-
Publishing model (See Model metrics.)
-
Self training the model (See Self training the model)
Keyword annotation
Keyword annotation refers to the activity of labelling unique words or a group of words available in the documents of the selected batch. Each word (or group of words) is further categorized under a given (or a new) category as per the requirements. (To know the purpose that keyword annotation serves, refer UWUC on this page.)
To perform keyword annotation, follow these steps:
-
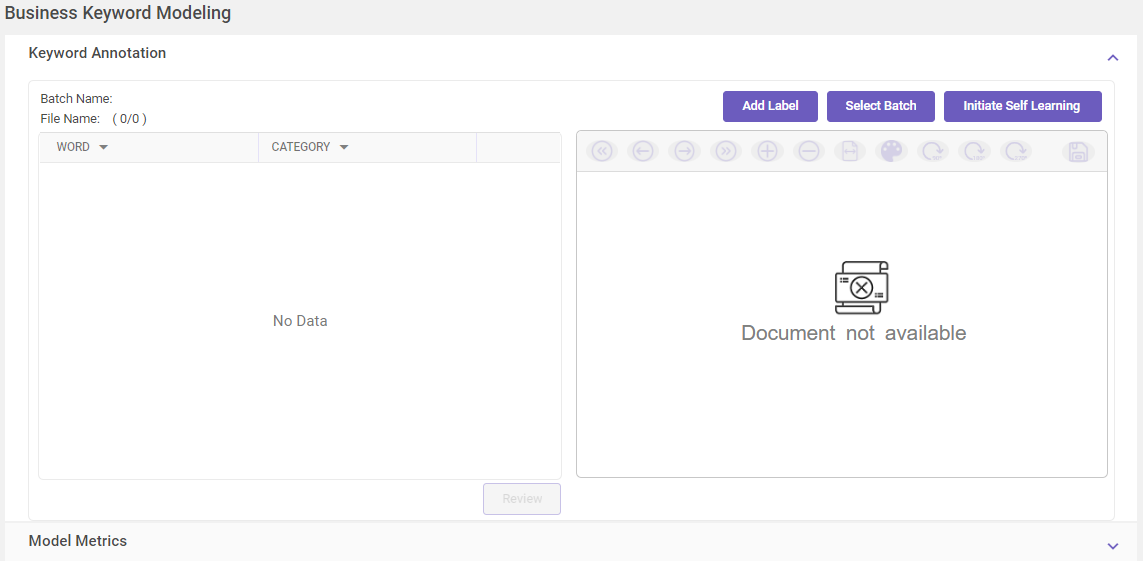
In the main menu, under TruCap+ Studio, click Business Keyword Modeling. The Keyword Annotation panel on the Business Keyword Modeling page opens.
-
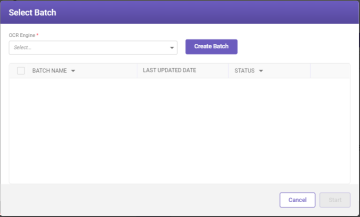
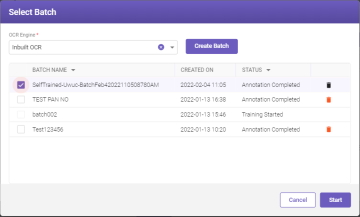
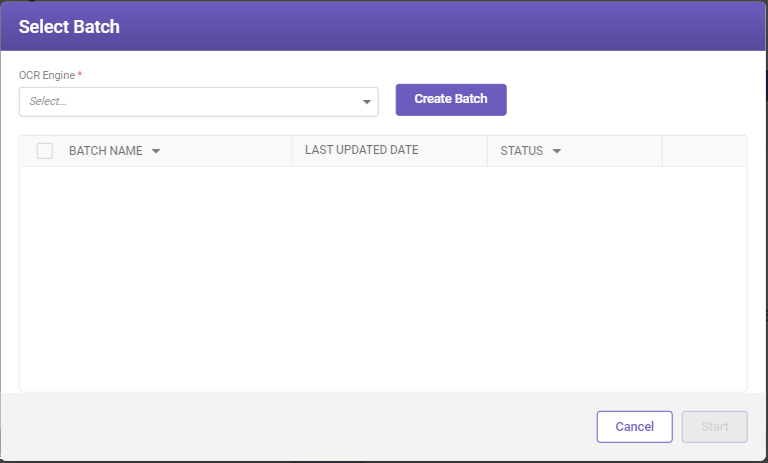
In the Keyword Annotation panel, click Select Batch to open Select Batch window.
-
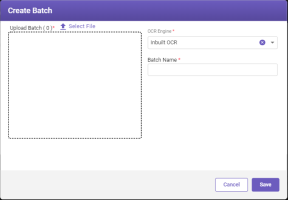
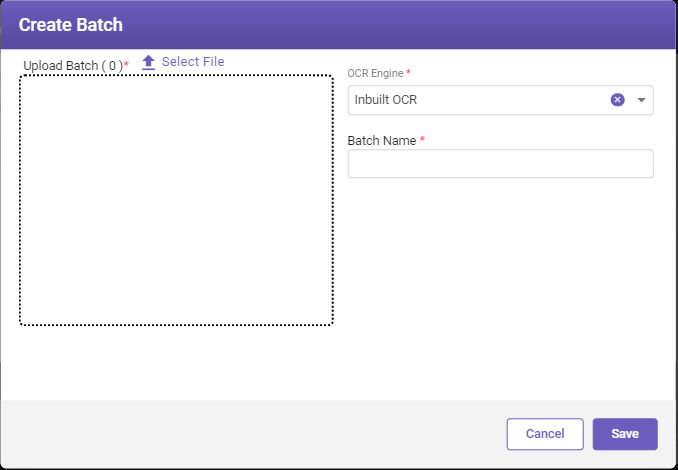
Select the required OCR Engine from the drop-down list and click Create Batch. The Create Batch window opens.
-
Specify the details based on the field descriptions provided in the below table.
FIELD
DESCRIPTION
Select File*
Link to be used to upload a single or a batch of documents (ZIP file).
Note: As business-keyword models are most effective to process documents of same type (for example invoice) and belonging to the same source, it is prudent to select files (documents) that are of same type and belong to a common source.
OCR Engine*
Select the required OCR Engine from the drop-down list.
Batch Name*
Name of the batch that contains the documents that are to be labeled.
Note: A batch can comprise of a single or multiple documents.
*Fields marked with asterisks are mandatory.
-
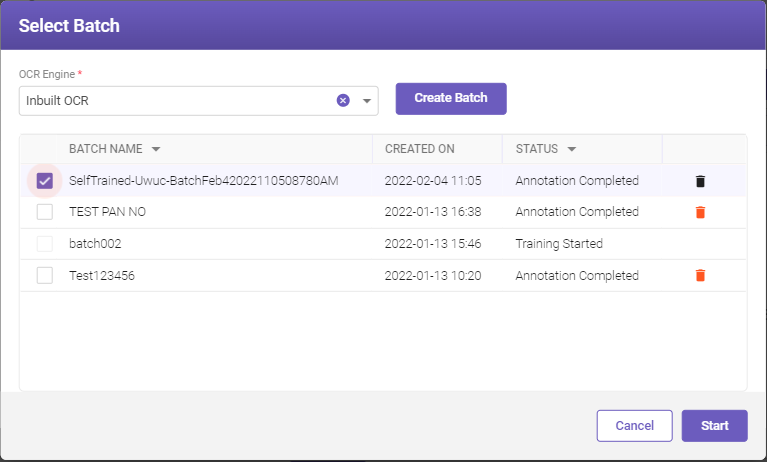
Click Save to create the batch. The batch appears in the Select Batch window.
-
Select the required batch in the Select Batch window, and then click Start as shown in the below figure. The batch of documents start getting processed and a message confirming the same appears on the screen.
-
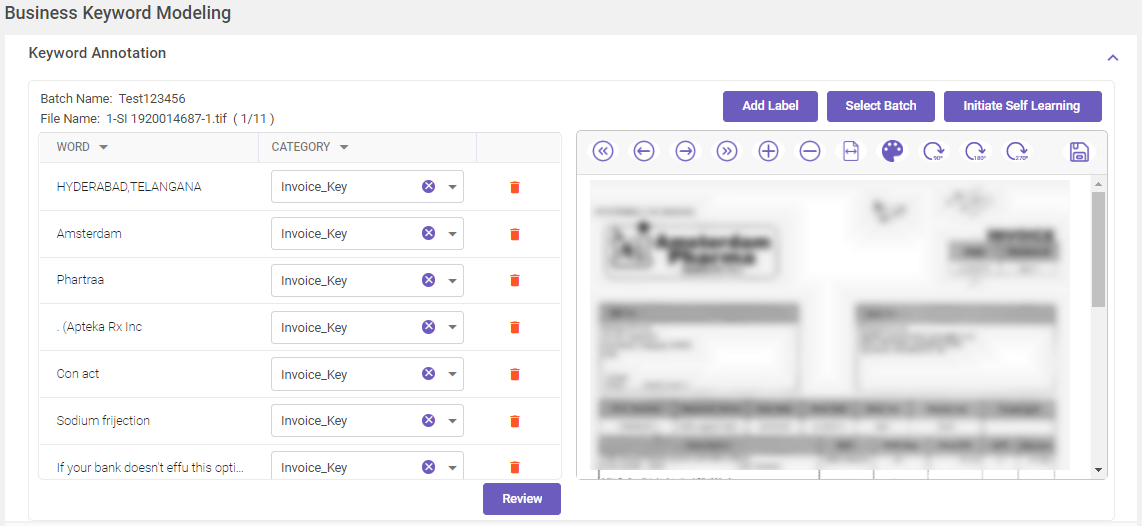
After the batch gets processed, the documents become available in the Keyword Annotation panel. You can use the features available on the taskbar to navigate the document, or to change the size of the displayed document, or to rotate the document, or mark ROI around the unique words (see image below).

Hover-over the above image to know about the available features.
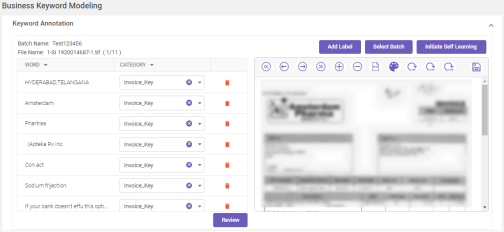
For each document, use
 to mark ROI around unique words (or group of words). As soon as you mark an ROI around a word, the word gets displayed under the WORD column in the panel. Select all such words that are unique to the document source such as SSN, PAN, telephone number, etc.
-
After marking the relevant words in all the documents, select a category for each word under the WORD column from the respective drop-down list under the CATEGORY header. You can also create a new category if required by clicking on Add a category available in the drop-down list.
Note:
-
To find the position of a listed word within a document, select the respective drop-down list. This will highlight the word within the document in the preview pane.
-
To create a business keyword model, an annotation should be applied to a minimum of 20 words under each category in a given batch.
-
To delete a word, use the delete
 icon next to the word.
-
To delete a category, go to Add Label and click on
 icon corresponding to the Master Label name. To edit a master label name click on
 icon corresponding to the Master Label name.
-
-
To save the keyword annotations for a given document, click
 above the preview panel. A success message will briefly appear on the page after annotations are saved.
-
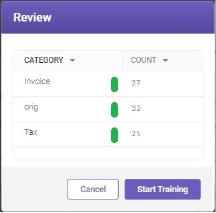
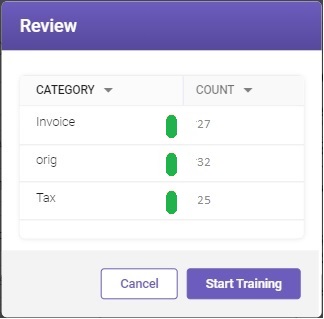
After you have saved the keyword annotations for the required documents in a batch, select Review to review the list of annotated keywords. The Review window will open, in which the annotations provided and their count is displayed.
Note:
A category will be flagged by a red mark if the count of words under it is less than 20. For model training, all the selected categories should have 20 or more words under them.
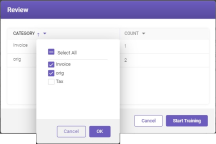
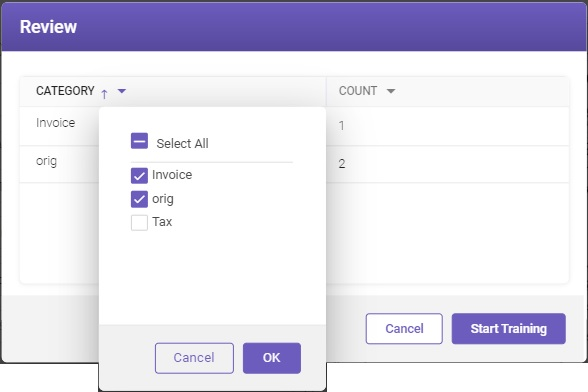
To include or exclude specific categories in the model, use the inverted arrow next to the CATEGORY header.
-
Click on Start Training. A message will appear on the screen confirming that the model is being trained. After it is trained, the model will appear under the Model Metrics panel ready to get published.
Model metrics
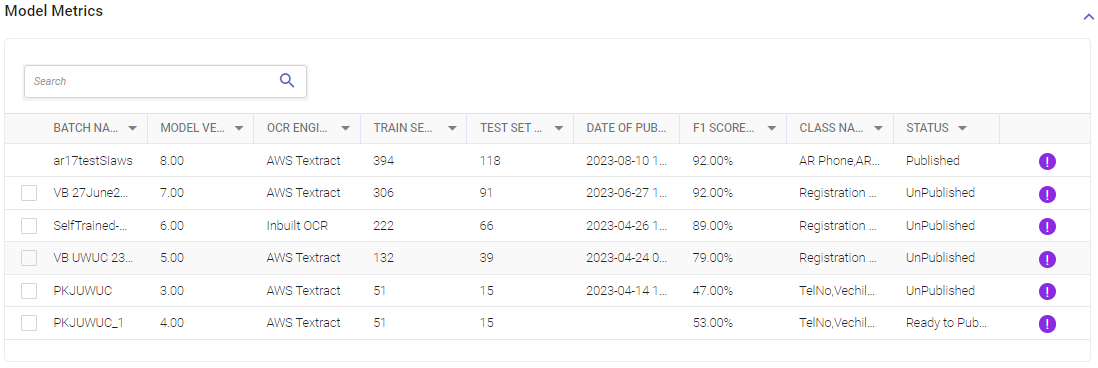
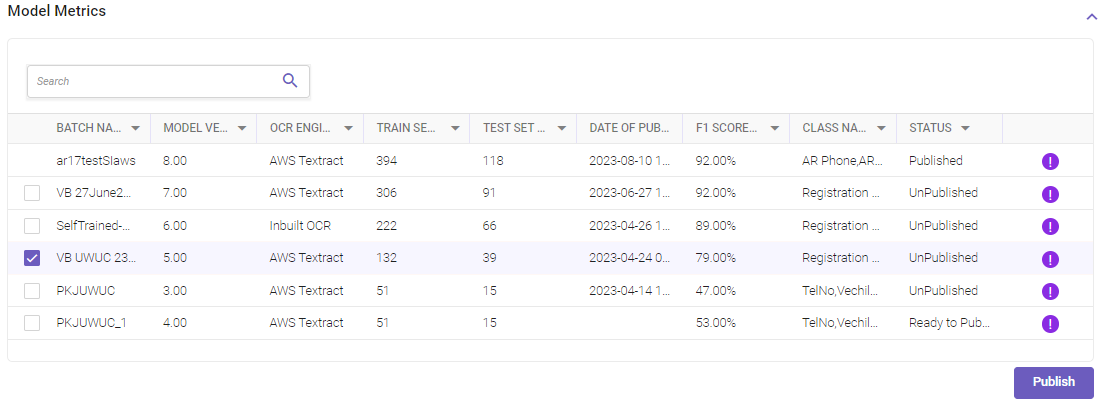
All the models that are either published or ready for being published are displayed under Model Metrics panel.
Column header descriptions
|
COLUMN NAME |
DESCRIPTION |
|---|---|
|
Batch Name |
Displays the name of the given model. |
|
Model Version |
Displays the version of the given model. |
|
OCR Engine |
Displays the name of the OCR engine used. |
|
Train Set File Count |
Displays the number of files that have been used to train the given model. |
|
Displays the number of files that were used to test the model. |
|
|
Date of Publish |
Displays the date when a given model was published. |
|
F1 Score/Accuracy |
Displays the accuracy results (in %) based on the test done on the available data. (See Test Set File Count column header.) |
|
Class Name |
Displays the class name to which the model is associated. |
|
Status |
Displays the current status of the batch. |
Note
Click  to display the number of annotations set that are categorized based on their type, say as SSN, PAN, invoice, etc. A Model Information pop-up showing the percentage and total number of annotations set is displayed (see below image).
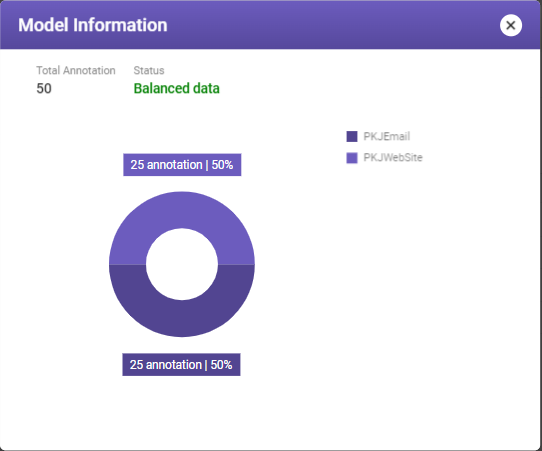
An ideal ML model must have an equal number of annotations set in each class for better accuracy. If not, then the model is treated as imbalanced. Depending on the accuracy, the status messages such as Balanced data, Low imbalance, and Highly imbalanced for the model are displayed. To know more about the status message, See example:
To publish models available in the panel, select them using the relevant filters next to each column header, and then click Publish. All the unpublished models available in the panel will get published.
Publishing a model
Publishing a model means to make it available to the application for use in processing the documents. Published models are applied for processing one-by-one starting from the earliest version (1.00) available to the latest until one of them provides a result. More
Note:
Removing a ML model is a permanent action, and once removed, the model cannot be recovered. If needed in the future, you'll have to either re-publish or re-train the model according to your requirements.
To remove a published model, follow these steps:
-
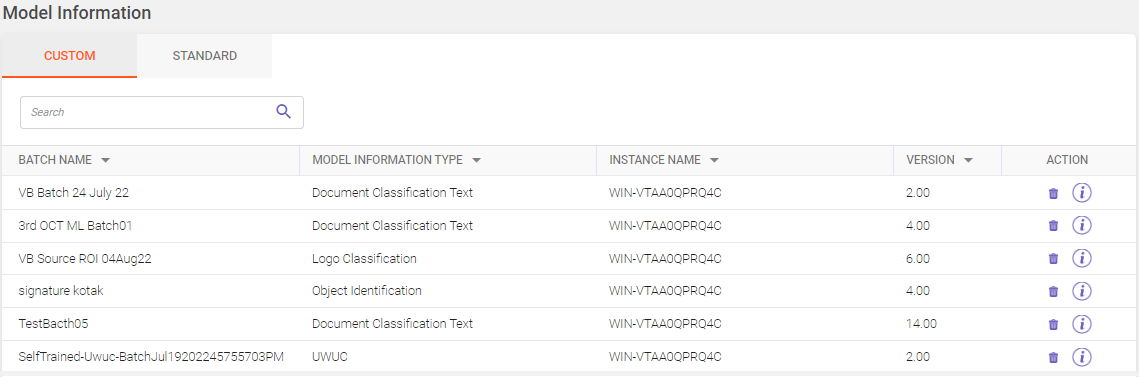
Access the Model Information page. This page provides a comprehensive overview of all the trained ML models available.

-
On the Model Information page, under the Custom tab, identify and find the UWUC ML model you wish to remove. Utilize the Search field to filter and find specific records within the displayed grid (Refer searching data).
-
Click
 under Action column corresponding to the UWUC ML model to remove the ML model. A Attention window opens.
-
Click Yes to permanently remove the ML model from the list. You can view the removed model on the Model Metrics page.
Re-publishing a model is a crucial step in ensuring that the latest improvements or modifications are reflected in its performance.
Note:
Before initiating the re-publishing process, carefully review the existing details of the model and make any necessary updates to align with your desired changes.
To re-publish a model, follow these steps:
-
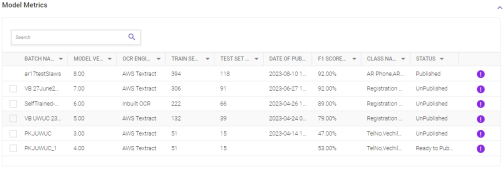
On the Model Metrics page, identify the ML model that you want to re-publish. Models that are not currently published will likely be displayed as UnPublished.
-
Select the unpublished model available in the panel, which you want to re-publish. A Publish button is visible. Utilize the Search field to filter and find specific records within the displayed grid (Refer searching data).
-
Click Publish to re-publish the model. Once published, the status of the model changes from UnPublished to Published indicating that the re-publishing process was successful.
You can view the published model on the Model Information page. Take a moment to review the details associated with the re-published model.
Self-training the model
The initiate self-learning feature of TruCap+ enables the user to self-train the application. The data for self-training the application gets generated automatically from the processed documents. Once the user initiates self-learning, all the processed documents' data gets added as a self-trained batch. The user can then annotate, train, and publish the self-trained batch.
To self-train a model, on the top-right corner of the Keyword Annotation panel, click Initiate Self Learning.